Which card for which language model?
A language model needs enough graphics memory (VRAM) for the model and its context. This table gives guide values.
Tip
For a specific model, our model calculator tells you the suitable card.
Guide values by model size
Small, up to 10 bn.
- Examples
- Qwen3.5 4B and 9B, Gemma 4 E4B, Granite 4.2 8B, Llama 3.1 8B
- Recommendation
- Tesla T4 16 GB or V100 16 GB
Medium, 14 to 32 bn.
- Examples
- Qwen3.8 27B, Gemma 4 31B, GLM-4.7-Flash, gpt-oss-20b
- Recommendation
- Tesla V100 32 GB
Large, from 70 bn.
- Examples
- Llama 3.3 70B, Apertus 70B, gpt-oss-120b
- Recommendation
- A100 80 GB or 2× V100 32 GB
Very large, from 120 bn.
- Examples
- Kimi K3, DeepSeek V4 Pro, GLM 5.3, Qwen3.5 397B
- Recommendation
- Server with several A100 80 GB or H100, on request
Suitable cards
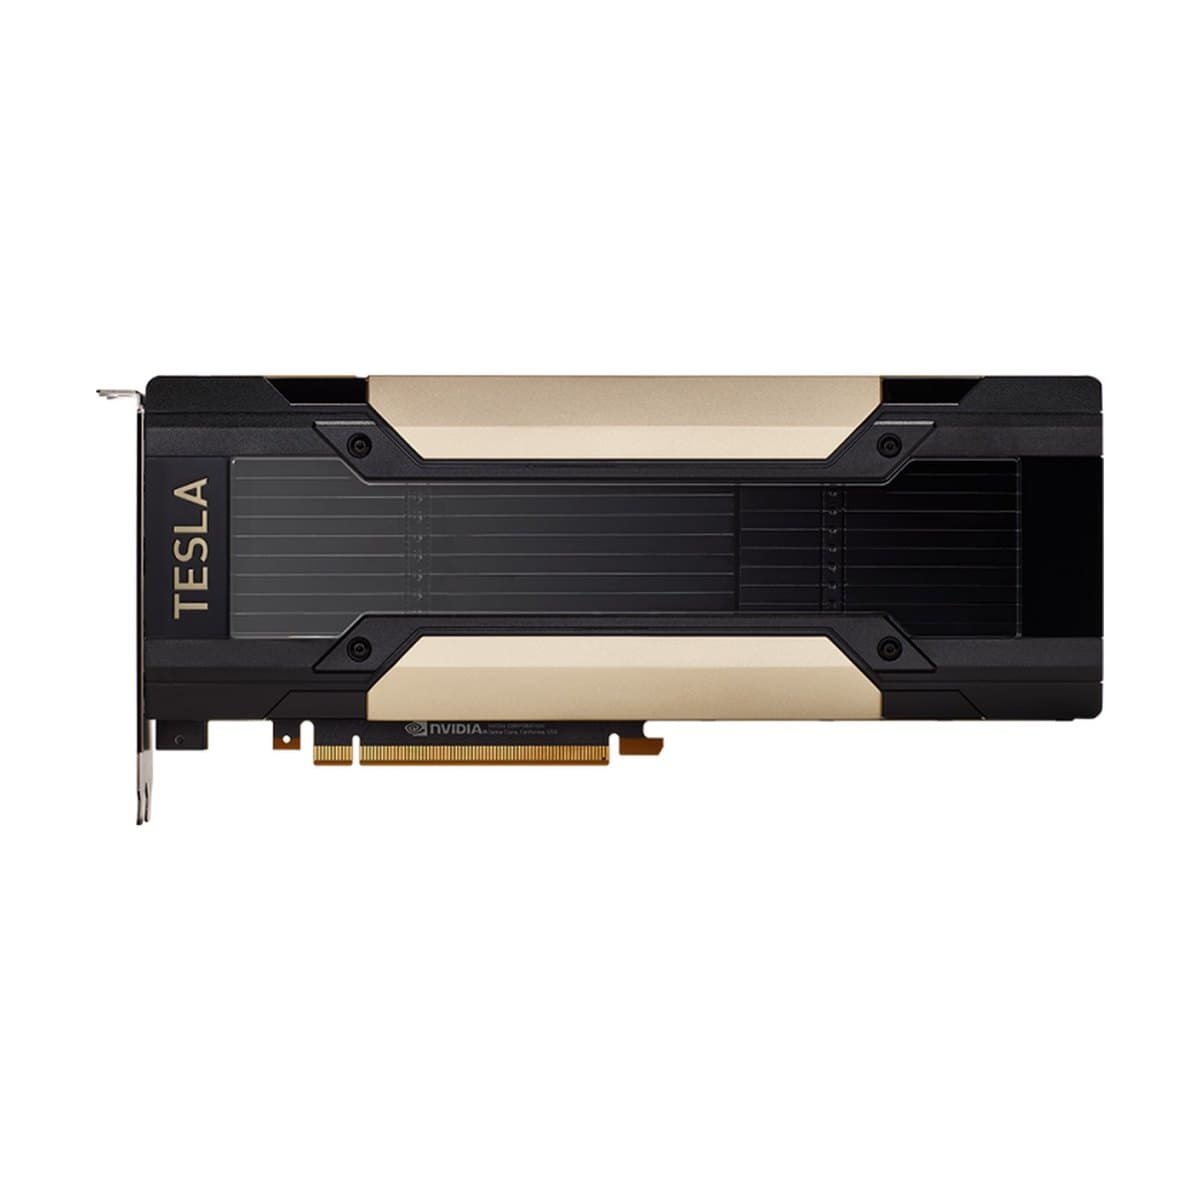
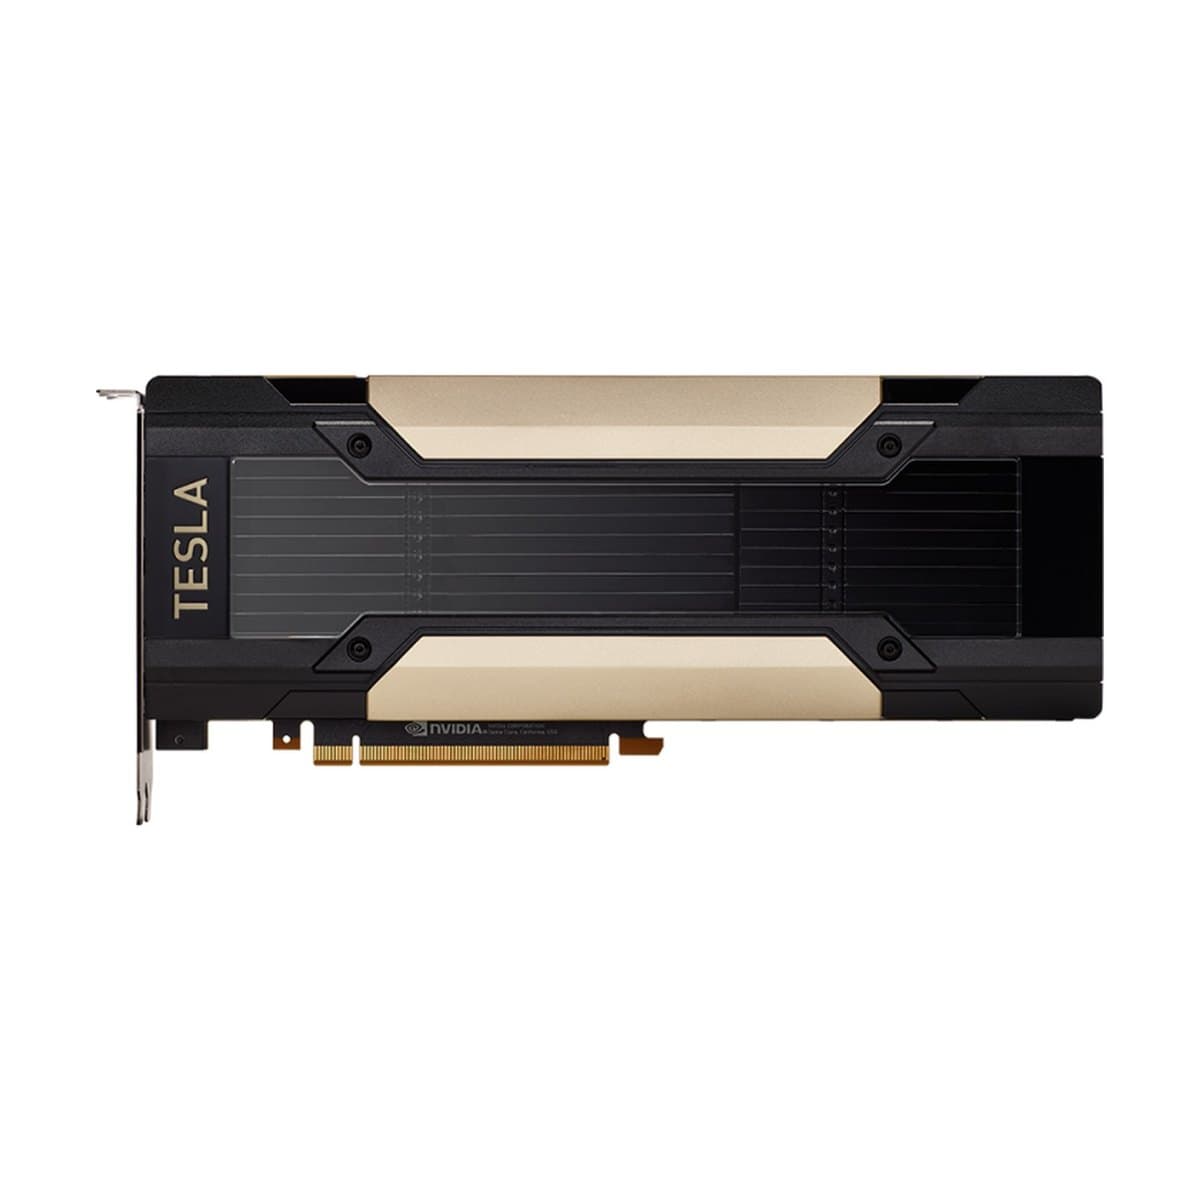
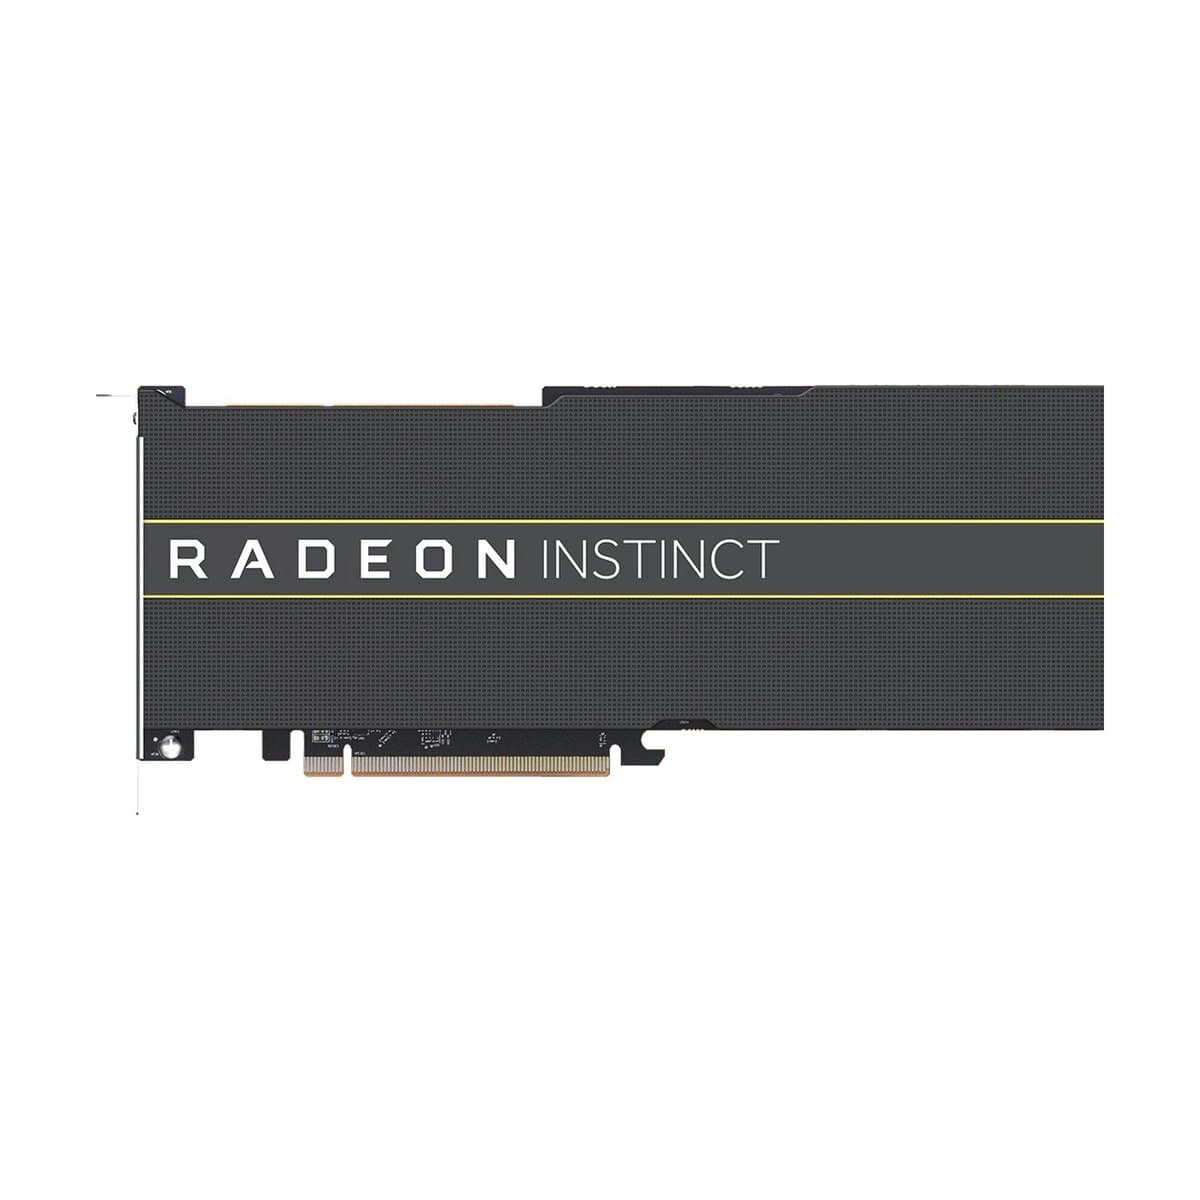
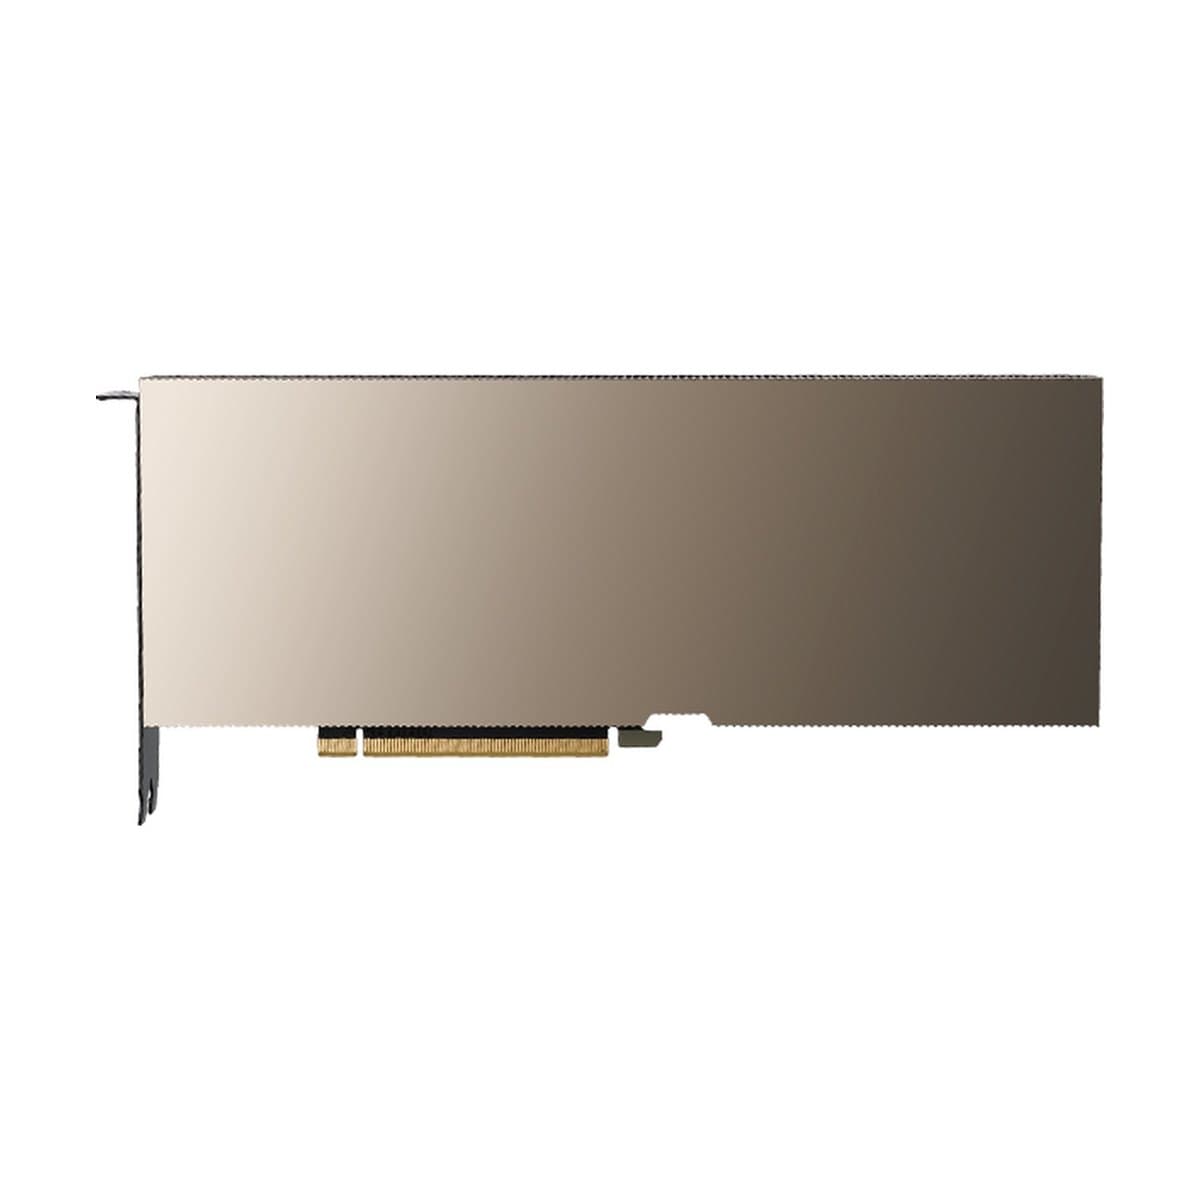
- With 4-bit quantization, models up to about 40 bn. parameters fit on a V100 32 GB.
- Llama 3.3 70B needs about 46 GB in 4-bit with 8k context.
- Several cards share the model, but do not become faster as a result.
Quantization
Models usually come in 16-bit precision. With quantization (e.g. 4 bit) the memory requirement drops to about a third, with little loss in quality.
| Format | Used in |
|---|---|
| Q4_K_M | llama.cpp, Ollama |
| AWQ / GPTQ | vLLM, Transformers |
Context and speed
| Term | Meaning |
|---|---|
| Context (e.g. 8k, 32k, 128k tokens) | How much text the model keeps in view at once. More context needs more VRAM and makes it slower. |
| Token speed | Depends on the memory bandwidth of the card. A V100 manages about 25 tokens/s with a 32B model. |
For individual advice or server configurations, get in touch with us.